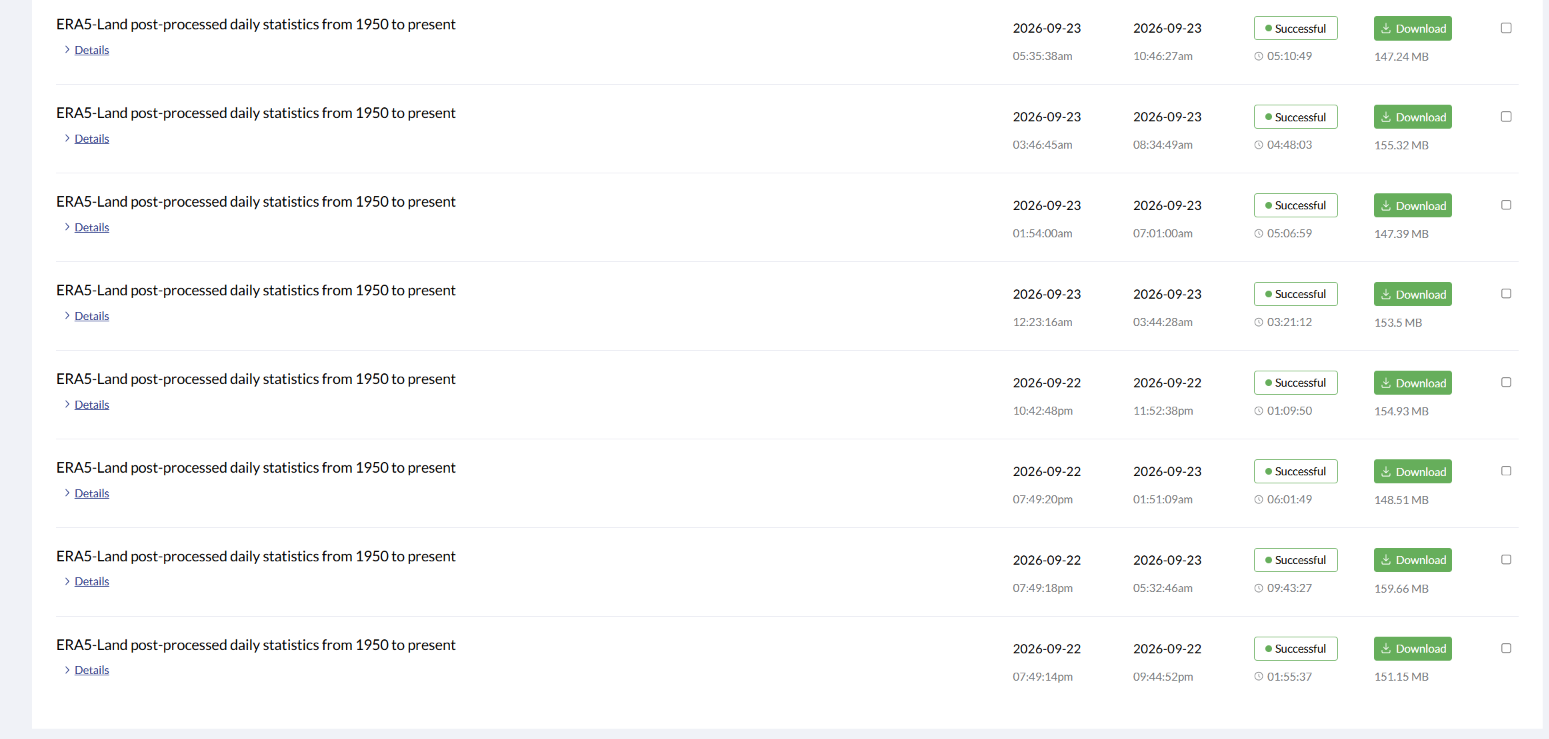
This is my first time using cdsapi to download global daily 2 m temperature data from the “ERA5-Land post-processed daily statistics from 1950 to present” dataset. I submit requests one month at a time, with three requests running in parallel, but each request spends at least two hours in the queue, and sometimes as long as nine hours. Is this normal? Are there any good ways to reduce the queue time?
Thank you!
Same here. It is highly time-consuming.
Yashwant,
climateanalyst@outlook.com
It’s the same issue with me as well. I have been downloading ERA5 pressure levels, and need them for 35 years (1990-2025). But the download request is so slow that it seems it will take at least 3-4 months to complete the download. When you start downloading, it takes nearly 2-3 minutes per download, but after 6-7 hours of running, it queues you for at least an hour. This needs to be rectified, or else it’s difficult to wait 3-4 months just for a few hundred MB of the dataset.
Hi,
you can maybe have a look at the ERA5 hourly time-series data on pressure levels from 1940 to present
the ERA5 pressure-levels dataset available in analysis-ready, cloud-optimised (ARCO) Zarr stores
A general suggestion is to send requests sequentially, wait for the first to finish and then send the next one.
Thanks
Hi Michela,
I guess we had a chat about it earlier. The ARCO dataset is indeed useful if we want 6-hourly data, which can still be interpolated to hourly via simple interpolation techniques, as the variables don’t vary much. But the pressure level jumps from 850 to 700 hPa, which is where I get most issues, as most of my area of interest lies in the altitude of 1500-3500 masl, and some interpolation over those levels gives an unrealistic jump in the derived variable.
Thanks.
Sometimes I get 20 requests / minute, sometimes 1. Can you make this system more reliable?